
Reflection AI introduced Beam, an open-weight model for agentic coding and long-horizon tasks such as maintaining code, using tools, interpreting results, and completing multi-step workflows. The open-weight release gives developers and researchers control over the runtime, deployment environment, and customization process.
In this post, we explain Reflection’s vision and show how you can deploy Beam on AWS. Start with an Amazon SageMaker JumpStart real-time endpoint for a fully managed path. When you need Kubernetes-native control over distributed GPU infrastructure, use Amazon SageMaker HyperPod Inference with JumpStart, SGLang, or vLLM. We also explain how Beam’s 501 billion total parameters shape checkpoint storage, weight memory, sharding, and parallelism, while its 23 billion active parameters influence per-token compute.
At launch, Beam is available in Amazon SageMaker JumpStart in US East (N. Virginia) and US East (Ohio).
Reflection’s vision for open intelligence
Reflection’s mission is to make intelligence open and accessible to all through open model weights, published research, and open source software. Its full AI stack spans models, core software, production infrastructure, and applications. Beam brings this approach to developers building software engineering and agentic systems.
About Reflection Beam
Beam is a sparse mixture-of-experts model for resolving software issues, modifying code, calling tools, and acting on intermediate results. It has 501 billion total parameters and 23 billion active parameters, and Reflection reports an effective context length of 1 million tokens.
Reflection releases Beam’s weights through Hugging Face under the Apache 2.0 license. Beam 1.0 is available in BF16, FP8, and NVFP4 checkpoint variants. These formats provide different memory footprints and hardware compatibility. You can deploy the model with the AWS managed JumpStart container configuration or inspect and customize the model with SGLang or vLLM in your AWS environment.
Understand the deployment architecture
Choose the serving path that meets your control and scaling requirements.
- Start with a SageMaker JumpStart real-time endpoint when you want an AWS managed model package, endpoint, and invocation API without operating Kubernetes.
- Use JumpStart on HyperPod Inference when you want the AWS managed container and model configuration on a HyperPod cluster orchestrated by Amazon Elastic Kubernetes Service (Amazon EKS).
- Use SGLang or vLLM on HyperPod Inference when you need to control the serving image, runtime arguments, quantization, or distributed execution.
- Size the deployment for checkpoint storage, weight memory, KV cache, context length, batching, runtime overhead, and the supported parallelism.
- Define the expected concurrency and latency targets, then configure replicas, caching, routing, and autoscaling from measured workload behavior.
The JumpStart real-time path packages the model, container, and endpoint behind a managed deployment workflow. The HyperPod path exposes the cluster and serving runtime so that you can control distributed execution, caching, routing, and scaling.
The following diagram shows the components used by the HyperPod path. Beam can be sourced through SageMaker JumpStart, Hugging Face Hub, or an optional Amazon Simple Storage Service (Amazon S3) mirror. The distributed workers use the AWS managed JumpStart container or a custom SGLang or vLLM runtime.
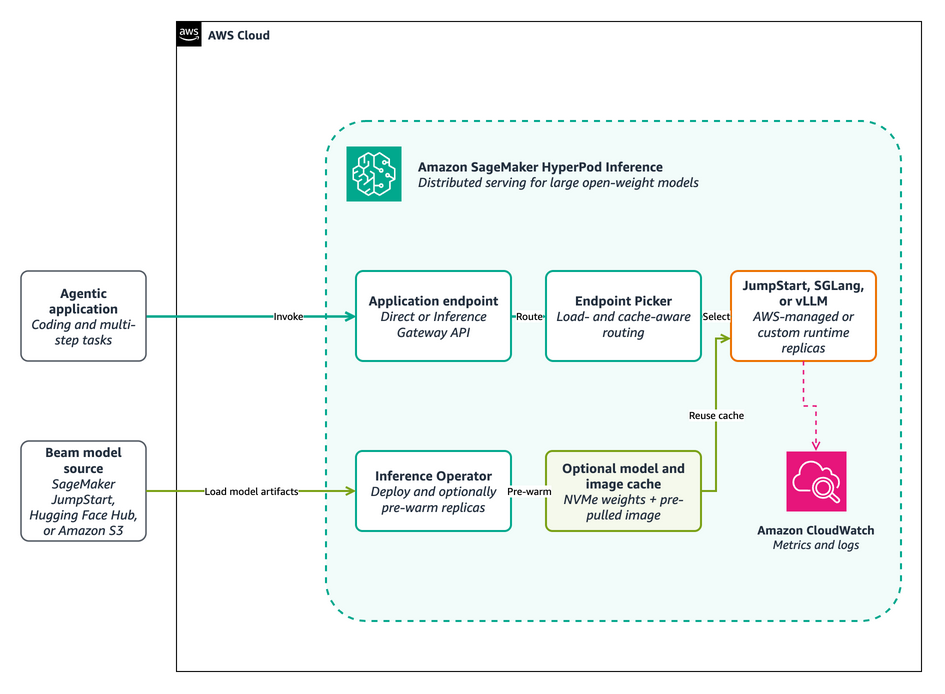
Figure 1: Distributed Beam deployment with Amazon SageMaker HyperPod Inference
Prerequisites
You need:
- An AWS account with permissions for your selected SageMaker deployment path and its supporting AWS Identity and Access Management (IAM), networking, and storage resources.
- Access to Beam through SageMaker JumpStart or one of the Beam 1.0 checkpoint repositories on Hugging Face.
- Acceptance of the model terms, the AWS Command Line Interface (AWS CLI), and Python 3.11 or later.
- GPU quota and capacity for a supported Beam configuration.
Plan and obtain GPU capacity
Beam’s 501 billion total parameters require a multi-GPU deployment. BF16 has the largest weight-memory requirement, so plan a multi-node configuration with enough aggregate GPU memory for the weights and runtime overhead. For FP8, use ml.p5.48xlarge with NVIDIA H100 GPUs or ml.p5e.48xlarge and ml.p5en.48xlarge with H200 GPUs. For NVFP4, use ml.p6-b200.48xlarge with NVIDIA B200 GPUs. Confirm that the released checkpoint, runtime, and parallel layout support the selected instance type.
- Calculate memory for weights, KV cache, and runtime overhead for one replica, then confirm the estimate with a load test.
- Choose an AWS Region that supports the required accelerated instance.
- Check the service quota and available capacity for the selected instance type. Use on-demand capacity when available, or use a SageMaker training plan as a short-term reservation for scheduled work.
- Allow time for image transfer, weight download, shard loading, and runtime initialization.
Path 1: Get started with a SageMaker JumpStart real-time endpoint
Use a JumpStart real-time endpoint first when you want the shortest path from the model catalog to a managed HTTPS endpoint. The sample supports the BF16, FP8, and NVFP4 model IDs through one variant-aware command. Its README and Python file are the source of truth for supported instance types, request schema, deployment command, and cleanup command.
- Clone the sample repository.
- Enter the SageMaker JumpStart deployment sample directory.
- Create and activate a Python virtual environment.
- Install the sample dependency.
- Run the bounded deployment, invocation, and cleanup lifecycle for FP8.
The command deploys the FP8 endpoint, sends a short request, prints the response, and cleans up the endpoint. Use
bf16ornvfp4to select another checkpoint variant; NVFP4 is the default when you omit--variant. Use the Python functions in the README when you need to keep an endpoint running.
Path 2: Deploy with SageMaker HyperPod Inference
Use HyperPod Inference when you need Kubernetes-native control over distributed GPU infrastructure. You can use the AWS managed JumpStart container configuration or deploy Beam with SGLang or vLLM. The HyperPod Inference deployment sample README and its configuration files are the source of truth for released manifests, model and image identifiers, supported runtime versions, and commands.
Before you begin, configure kubectl access to an EKS-orchestrated HyperPod cluster with the HyperPod Inference Operator and required add-ons. You also need the cluster virtual private cloud (VPC), subnets, security groups, access to the selected Beam and runtime artifacts, and local NVMe capacity if you enable model caching. Use an isolated Hugging Face access token if the selected repository requires authentication.
Deploy a pinned Beam revision from Hugging Face Hub for development and experimentation. For production deployments and model caching, copy the checkpoint to Amazon S3 or Amazon FSx. HyperPod model and image caching can preload weights onto node-local NVMe storage and pre-pull the serving image.
The HyperPod Inference Gateway provides an OpenAI-compatible interface and routes requests across replicas. HyperPod Inference also supports managed tiered KV caching and intelligent routing. These are among the Amazon SageMaker Inference capabilities introduced in 2026.
The next diagram expands the model preparation and runtime request flow. When model caching is enabled, the Inference Operator warms eligible nodes with the selected weights and serving image. At runtime, the Inference Gateway and Endpoint Picker can direct each request to a suitable JumpStart-managed, SGLang, or vLLM replica.
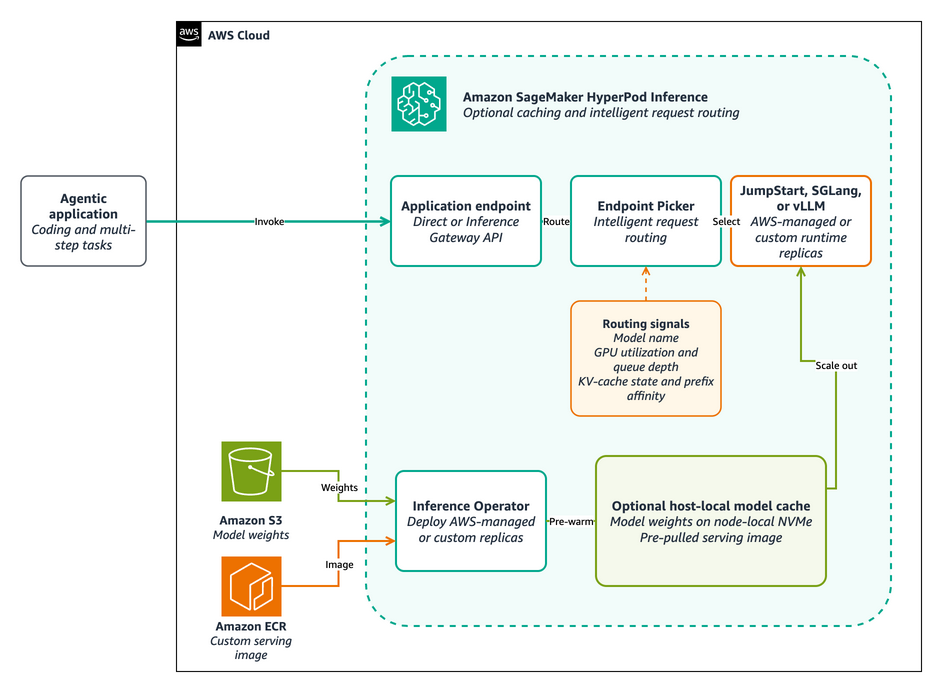
Figure 2: HyperPod model caching and request routing
Prepare deployment artifacts
Use immutable inputs so that you can reproduce deployment and performance results.
- Use the JumpStart model release recorded in the deployment sample.
- Choose the BF16, FP8, or NVFP4 checkpoint for a custom runtime.
- For a custom runtime, keep the public Beam commit SHA and image digest in the sample release configuration.
- Mirror the released image into a private Amazon Elastic Container Registry (Amazon ECR) repository only when your cluster cannot pull the upstream image or your organization requires an approved registry.
- Keep tokens, generated secrets, private model IDs, registry credentials, and unpublished results out of the repository.
Choose a serving path
Start with SageMaker JumpStart unless your workload requires a specific inference runtime or configuration.
| Serving path | Use it when | What you manage |
| SageMaker JumpStart | You want an AWS-managed container and model configuration with less runtime maintenance. | Select the Beam model version, supported instance type, endpoint configuration, and scaling policy. |
| SGLang or vLLM | You need a specific inference runtime or configuration, such as custom runtime arguments, parsers, quantization, or parallelism. | Pin the supported runtime image, model revision, parser configuration, and distributed execution settings. |
Deploy with SageMaker JumpStart
SageMaker JumpStart reduces container integration work while HyperPod retains control over cluster capacity, scaling, and observability.
- In SageMaker Studio, open the JumpStart model catalog.
- Under All public models, choose Beam.
- Choose SageMaker HyperPod as the deployment target.
- Select the cluster and Kubernetes namespace.
- Enter an endpoint name, and choose Deploy.
- Confirm the deployment status before invoking the endpoint with the released JumpStart request schema.
For an infrastructure-as-code workflow, use the released JumpStart configuration in the HyperPod sample. You can inspect the reflection-beam-jumpstart.yaml manifest template before configuring the deployment.
- Clone the sample repository, and enter the HyperPod Beam directory.
- Create the local configuration files described in the README.
- Validate the JumpStart configuration before changing the cluster.
- Deploy the JumpStart configuration.
The helper renders and applies the released JumpStartModel resource without writing populated release values to disk.
Deploy with SGLang or vLLM
Choose SGLang or vLLM when you need direct control over the serving runtime. Before configuring the deployment, inspect the reflection-beam-sglang.yaml manifest template or the reflection-beam-vllm.yaml manifest template. The sample README remains the source of truth for released values and commands.
- Clone the sample repository.
- Enter the HyperPod Beam directory.
- Create the local configuration files described in the README.
- Validate the selected configuration before changing the cluster.
- Deploy Beam, and wait for a terminal deployment state.
Replace
sglangwithvllmto use vLLM. The helper validates the selected settings, applies the rendered manifest without writing release values to disk, waits with a fixed timeout, and prints diagnostics if deployment fails.
Invoke Beam
Invoke JumpStart endpoints with the released model request schema. For SGLang or vLLM, use the bounded smoke test included in the HyperPod sample.
Invoke the deployed endpoint
- Install the sample client dependency.
- Run a private health check and short request with the recommended starting sampling settings.
Replace
sglangwithvllmfor a vLLM deployment. The helper selects a ready worker, opens a temporary port-forward, checks endpoint health, sends the request, and closes the port-forward.
The response resembles the following:
For an authenticated Inference Gateway, use the bearer-token procedure in the HyperPod sample README. Keep credentials out of source code, manifests, and command history.
Measure and tune performance
- Test each serving path with repeated, representative coding and tool-use requests at the expected concurrency.
- Record the Beam model version, image digest, instance type, precision, context length, parallelism, serving arguments, cache state, and test repetitions.
- Measure request success rate, p50 and p95 time to first token, time per output token, end-to-end latency, and aggregate output tokens per second.
- Tune batch size, KV cache allocation, replica count, autoscaling, and model and image caching from those results.
- Recheck output quality after changing precision or quantization.
Clean up
Delete resources when you finish testing to avoid ongoing charges.
- For a SageMaker JumpStart real-time endpoint, follow the cleanup instructions in the SageMaker JumpStart deployment sample README.
- For JumpStart, SGLang, or vLLM on Amazon SageMaker HyperPod Inference, follow the cleanup instructions in the HyperPod Inference deployment sample README.
- Delete a dedicated HyperPod or Amazon EKS cluster created for the walkthrough.
- Delete unused cached weights, mirrored artifacts, load balancers, log groups, temporary IAM roles, and captured inference data.
Conclusion
Reflection Beam gives developers an open-weight model designed for agentic coding and multi-step tasks. Start with a SageMaker JumpStart real-time endpoint for a fully managed deployment. Use SageMaker HyperPod Inference with JumpStart when you need Kubernetes-native infrastructure control without managing the serving container, or choose SGLang or vLLM when you need a custom runtime.
Use the SageMaker JumpStart deployment sample or the HyperPod Inference deployment sample, then follow the instructions.
To learn more about Reflection AI and its vision for open intelligence, visit Reflection AI and read Introducing Beam.
Resources
About the authors