
uniopen is a digital communication and membership platform launched by Taiwan’s Uni-President Enterprises Group, connecting customers to ecommerce, membership benefits, and other retail experiences across web, tablet, and mobile channels.
Across those channels, uniopen applies a moderation policy that classifies each interaction along two axes. The first is what behavior occurred (nine categories), and the second is what subject the behavior refers to (brand, other, or forbidden). Both must be correct for a moderation decision to be useful, and both are specific to uniopen’s business rather than something a general-purpose model can be expected to learn out of the box.
In this post, we show how the team adapted Amazon Nova 2 Lite to these business-specific moderation policies through supervised fine-tuning in Amazon SageMaker AI and a final prompt-level output optimization. The AWS approach kept correction data, managed training, evaluation, and deployment controls in one repeatable workflow. Model availability varies by AWS Region. See Supported models by AWS Region in Amazon Bedrock.
Figure 1 shows the web, tablet, and mobile experiences covered by this moderation policy.
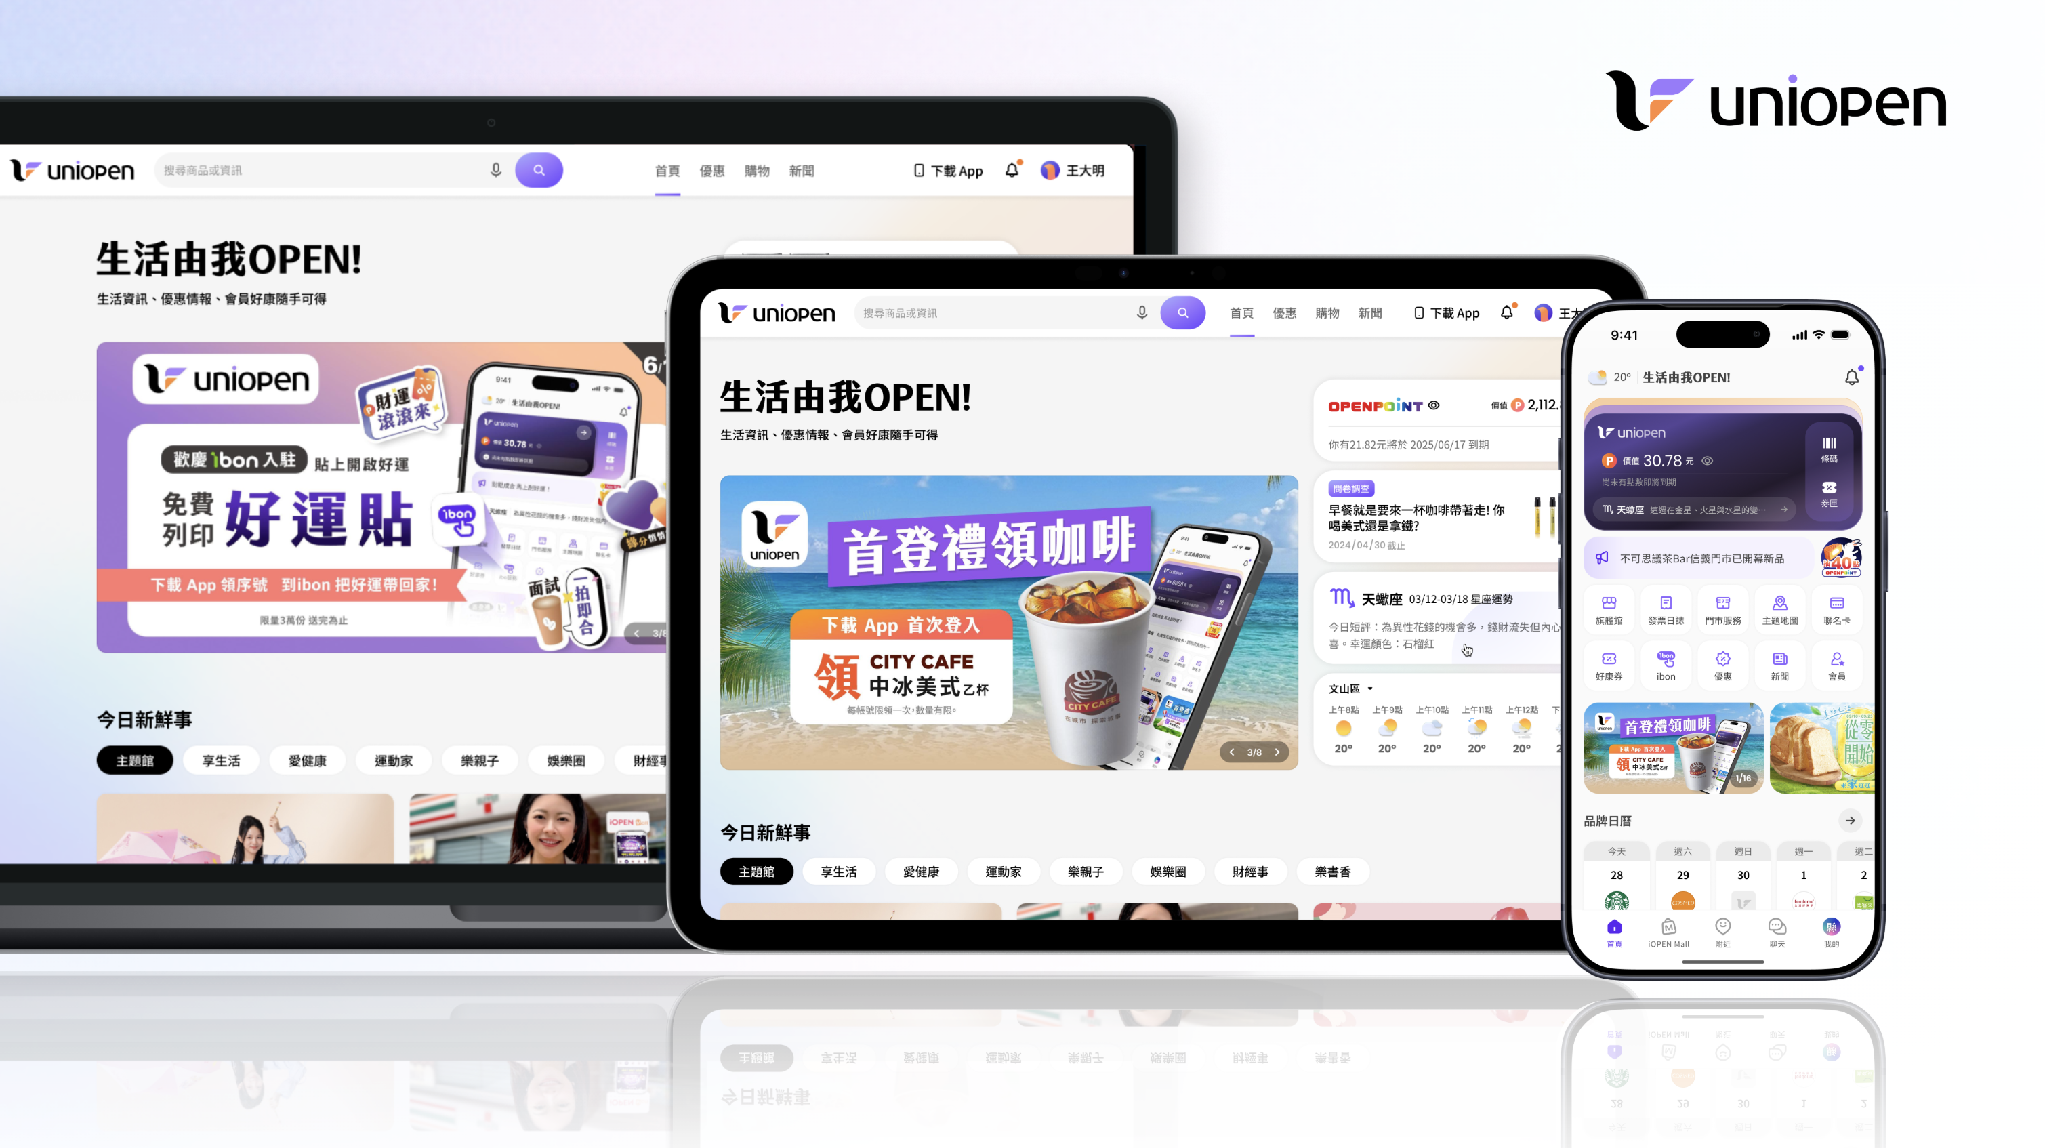
Figure 1: uniopen digital experience across web, tablet, and mobile channels
Across these channels, the same moderation taxonomy and release criteria help the team make consistent decisions as interaction formats and topics change.
Solution overview
The architecture separates the production moderation path from correction, training, evaluation, and deployment. Amazon Nova 2 Lite handles the primary moderation requests. Amazon Nova 2 Pro supports candidate correction generation for reported errors, but a human reviewer must verify each correction before it can enter the training set. With this separation, the team can improve domain-specific behavior without treating generated labels as ground truth.
Amazon Simple Storage Service (Amazon S3) stores the verified correction set and training data. Amazon DynamoDB tracks active and candidate model configurations. Argo Workflows on Amazon Elastic Kubernetes Service (Amazon EKS) orchestrates prompt optimization, evaluation, and deployment, and Argo CD applies approved configurations to production. Amazon Simple Notification Service (Amazon SNS) and Amazon CloudWatch notify operators when a hard gate fails or a candidate needs attention. These managed AWS components keep data, training, configuration state, and operational controls in a governed workflow.
Responsible AI controls complement model customization. Human review remains mandatory for ambiguous cases and for corrections reused as training data. Fixed test sets and regression checks prevent automatic promotion when quality declines. Teams can also apply Amazon Bedrock Guardrails content filters to inputs and outputs, monitor errors across behavior and subject categories, minimize retained customer data, and revalidate thresholds as moderation policies change.
Figure 2 shows how a reported error becomes a human-verified correction, enters the Amazon S3 correction set, and triggers the evaluation and deployment workflow.
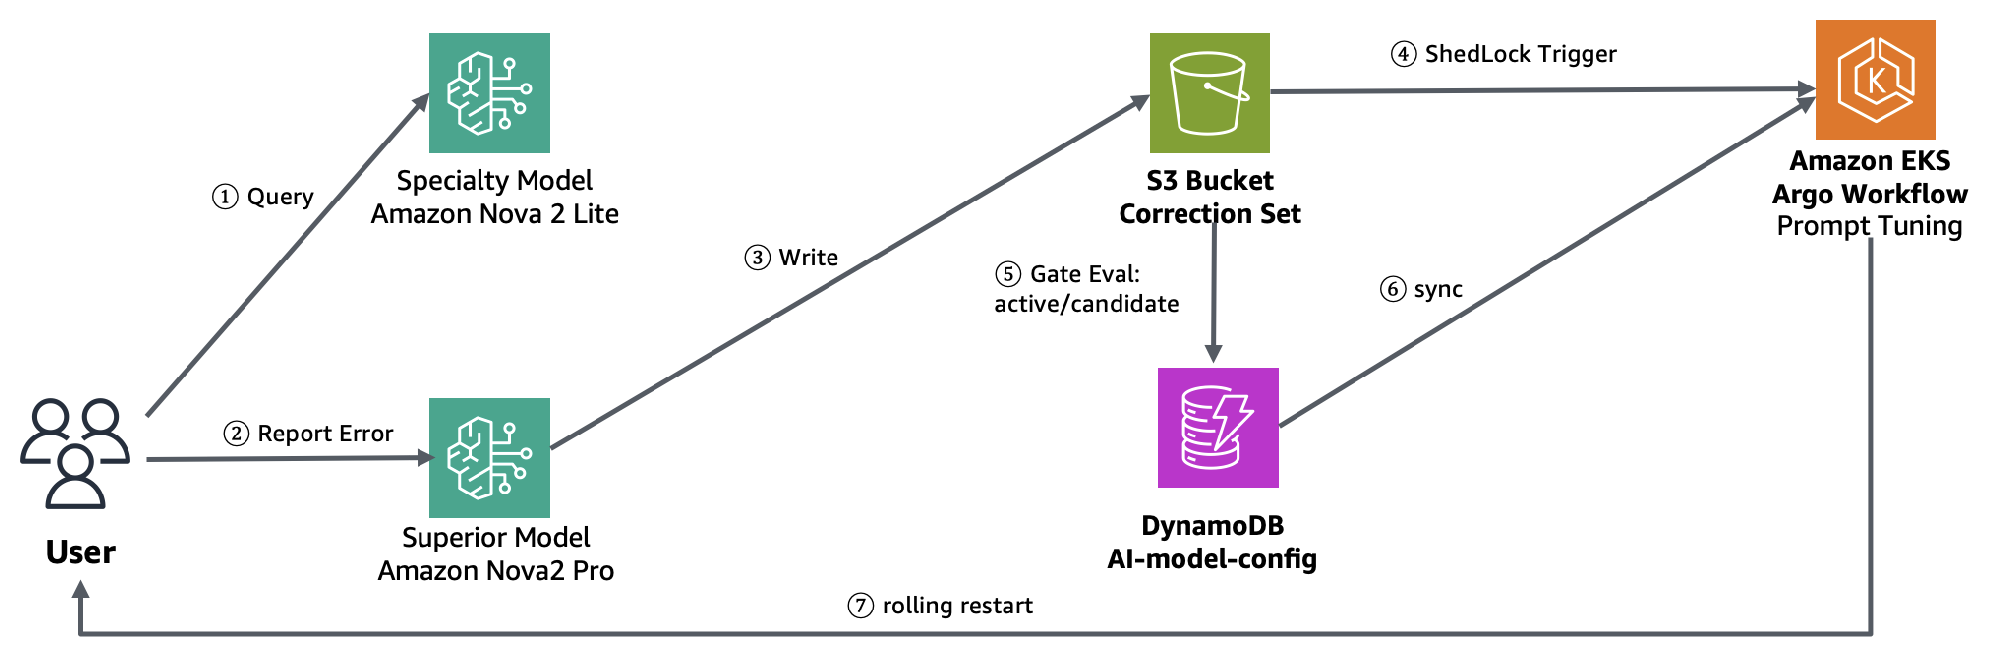
Figure 2: Human-verified feedback loop for continuously improving retail content moderation
The user first queries the active Amazon Nova 2 Lite configuration. When the user reports an error, the correction workflow creates a candidate label, obtains human verification, and writes the approved example to Amazon S3. The orchestration workflow reads the correction set, creates a candidate prompt or customized model, evaluates it, and updates DynamoDB only after the candidate passes the required gates.
Figure 3 expands the hard- and soft-gate decision path that controls whether a candidate stops, waits for human approval, or moves into production.
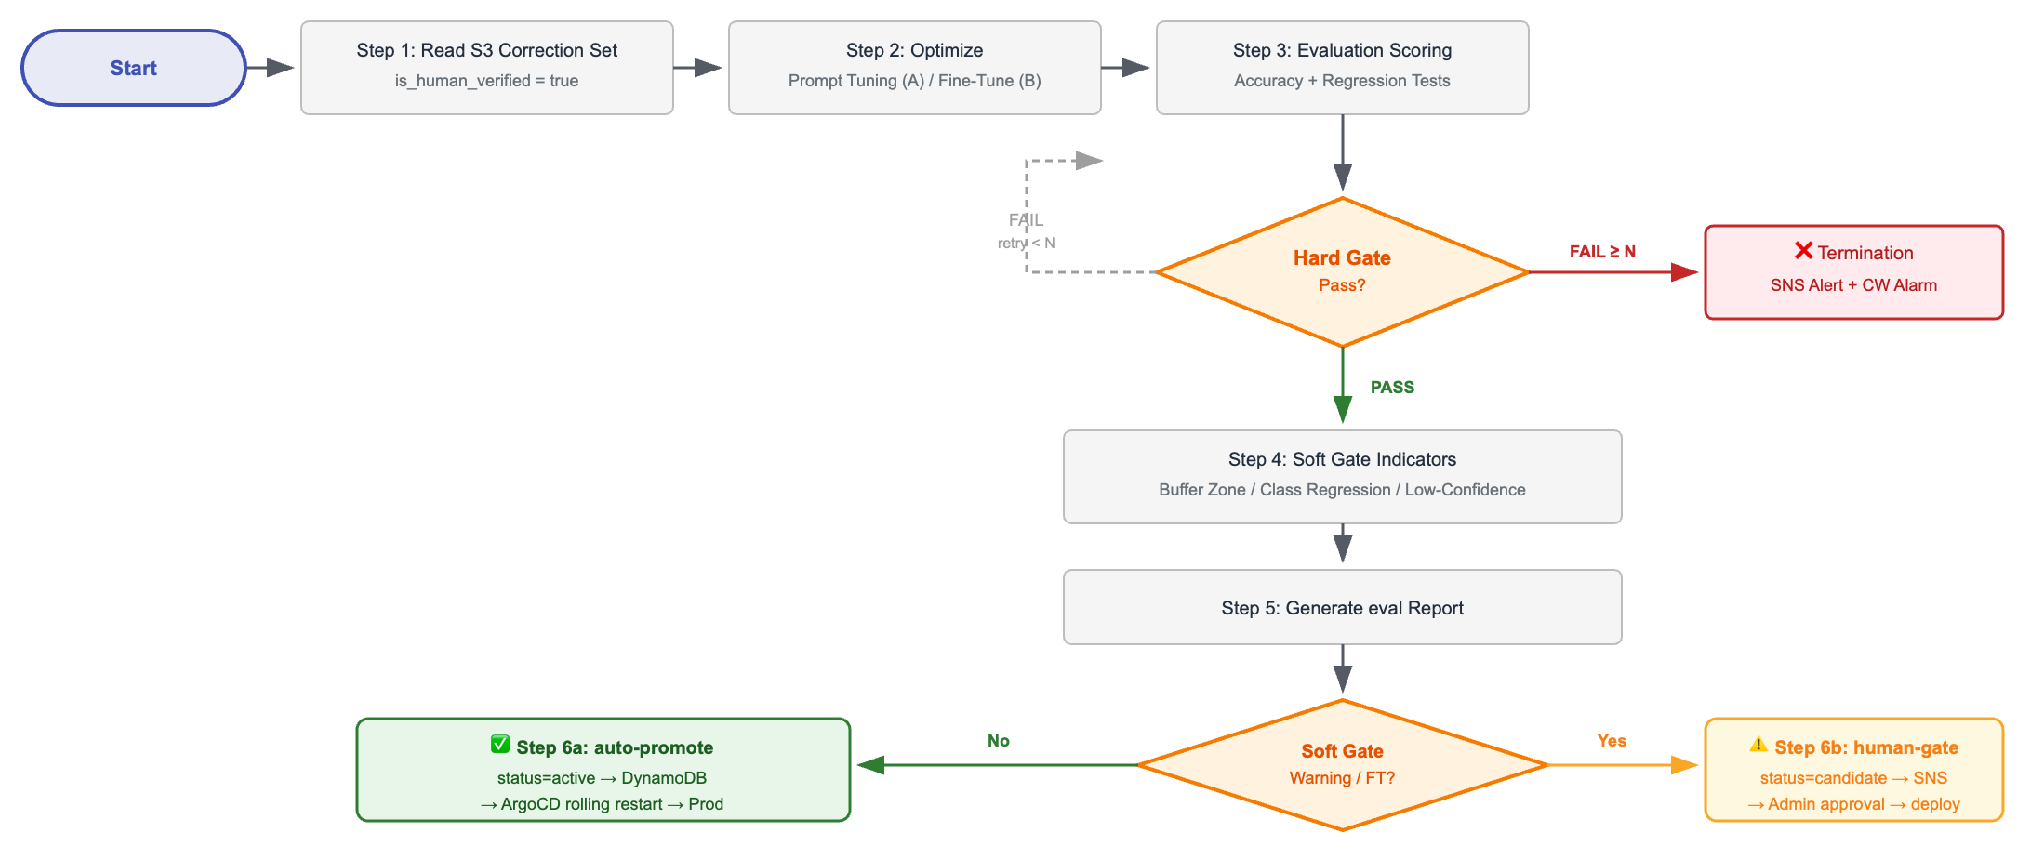
Figure 3: Hard and soft gate evaluation flow used to control model and prompt promotion
Two kinds of checks control promotion: hard gates and soft gates. Hard gates are must-pass regression tests. Soft gates are warning signals such as low confidence or a drop in performance for a specific class.
A hard-gate failure stops the workflow and sends an alert. Candidates that pass the hard gate are then checked for soft-gate indicators. If no warning is detected, the candidate can be promoted automatically. If a soft-gate warning is triggered, the candidate remains pending and requires administrator review and approval before deployment.
Evaluation approach
A conversation window is a bounded segment of a customer conversation that is treated as one training or evaluation example. All three configurations were evaluated on the same held-out test set of 737 conversation windows. The fine-tuning dataset contained 3,391 training windows. The team compared the baseline model, the fine-tuned model, and the prompt-optimized fine-tuned model on this consistent test set.
Per Behavior Macro F1 measures how consistently the model classifies the nine moderation behaviors as a group. Each behavior contributes equally to the score, so strong performance on common or easier categories can’t hide weak performance on harder categories. For uniopen, this matters because the moderation system needs to work across the full policy set, not only the most frequent behavior.
Subject Type Macro F1 measures how consistently the model identifies the type of subject involved: brand, other, or forbidden. Each subject type contributes equally to the score. This matters because a moderation decision is more useful when the system not only detects a policy-relevant behavior but also correctly understands what entity the behavior refers to. Together, the two metrics show policy detection and subject understanding on the same 0-1 scale.
Baseline performance
The base model established a useful baseline, but it still showed a significant gap in learning uniopen’s specific moderation taxonomy. Without fine-tuning, Amazon Nova 2 Lite achieved a Per Behavior Macro F1 of 0.5852 and a Subject Type Macro F1 of 0.4162. These scores show that the model had not yet learned uniopen’s specific moderation taxonomy well enough for production use.
Amazon SageMaker AI customization
The team then customized Amazon Nova 2 Lite using supervised fine-tuning with Low-Rank Adaptation (LoRA) in Amazon SageMaker AI. Fine-tuning allowed the model to learn from task-specific examples instead of relying only on prompt instructions. Figure 4 shows the completed Amazon SageMaker AI training job and the recorded configuration used for the customization run.
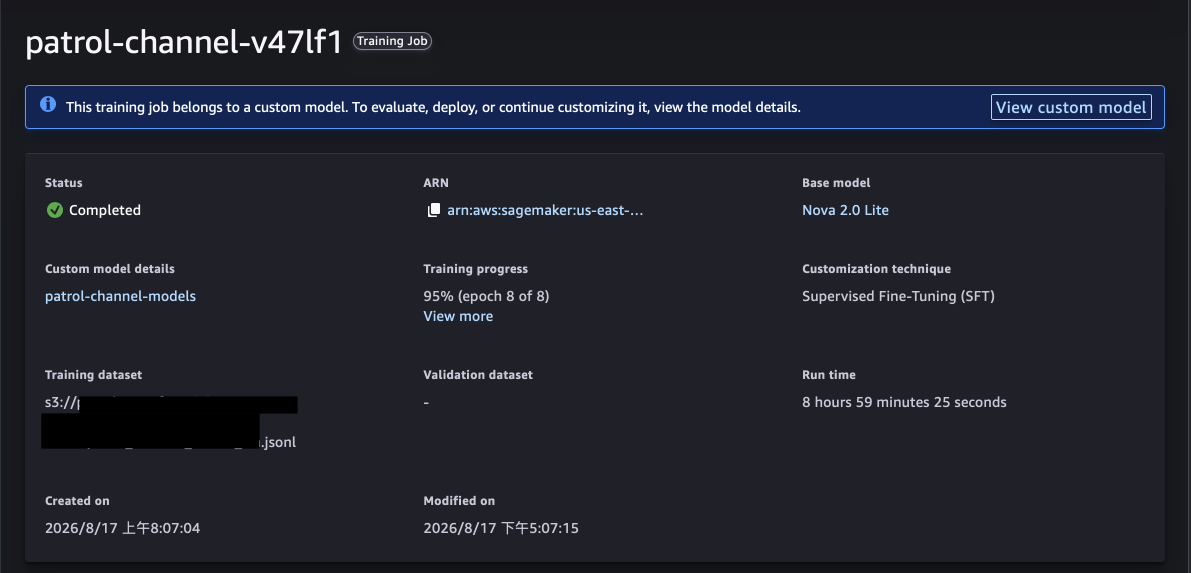
Figure 4: Amazon SageMaker AI supervised fine-tuning job for Amazon Nova 2 Lite
The training-job record captures the base model, customization technique, training-data location, run time, and progress for audit and repeatability. Fine-tuning delivered the largest performance gain. Per Behavior Macro F1 increased from 0.5852 to 0.8364, while Subject Type Macro F1 increased from 0.4162 to 0.8302. The subject-type metric exceeded its production target, while behavior classification moved close to its target.
Prompt optimization
After fine-tuning, the team made a prompt-level change to simplify the model output from JSON to a line-based format and clarify how multiple behaviors should be returned. This change required no additional model training.
The prompt optimization increased Per Behavior Macro F1 from 0.8364 to 0.8550 and Subject Type Macro F1 from 0.8302 to 0.8491. With this final step, both metrics exceeded their production targets of 0.8500 and 0.8200, respectively.
Results
Table 1 summarizes performance for the Amazon Nova 2 Lite baseline, the Amazon SageMaker AI fine-tuned model, and the prompt-optimized fine-tuned model.
Table 1: Classification performance across optimization stages
| Metric | Baseline | Fine-tuned (JSON) | Prompt-optimized (LF) | Production target |
| Per Behavior Macro F1 | 0.5852 | 0.8364 | 0.8550 | ≥ 0.8500 |
| Subject Type Macro F1 | 0.4162 | 0.8302 | 0.8491 | ≥ 0.8200 |
The two metrics exposed different weaknesses at each stage. The baseline needed improvement in both behavior detection and subject understanding. Amazon SageMaker AI fine-tuning produced the largest gain, especially in Subject Type Macro F1, showing the value of domain-specific examples for uniopen’s taxonomy. Prompt optimization then moved both metrics above their production targets without another training run. Using both metrics as release gates prevented an improvement in one dimension from hiding a regression in the other.
After both metrics cleared their release targets, uniopen could direct routine moderation to the customized path and keep human review focused on ambiguous cases. This operating model reduces unnecessary escalation while preserving a human decision point for uncertain or policy-sensitive content.
Next steps
The team will continue using Per Behavior Macro F1 and Subject Type Macro F1 as production gates. It will collect new boundary cases from real traffic and use those cases to decide whether the next improvement should be a prompt change or another targeted fine-tuning cycle. The same evaluation pattern can extend to additional retail moderation scenarios while human reviewers remain focused on ambiguous cases.
Conclusion
uniopen’s results show how business-relevant evaluation can identify where a foundation model needs adaptation. Supervised fine-tuning addressed domain-specific classification gaps, and prompt optimization captured additional gains without another training run. The repeatable pattern is to measure, identify the weaker dimension, apply the targeted change, and promote only when every release gate passes.
To explore the services and techniques in this post, visit the Amazon SageMaker AI service page, read the Amazon Nova fine-tuning documentation, and review Prompting Amazon Nova 2 for content moderation. For production safeguards, see the Amazon Bedrock Guardrails documentation.
About the authors